Linear programming with the optimum as a typed constant. More...
#include <array>#include <concepts>#include <cstddef>#include <limits>#include <span>import dedekind.sets;import dedekind.linear_algebra;import dedekind.numbers;import dedekind.category;import dedekind.algebra;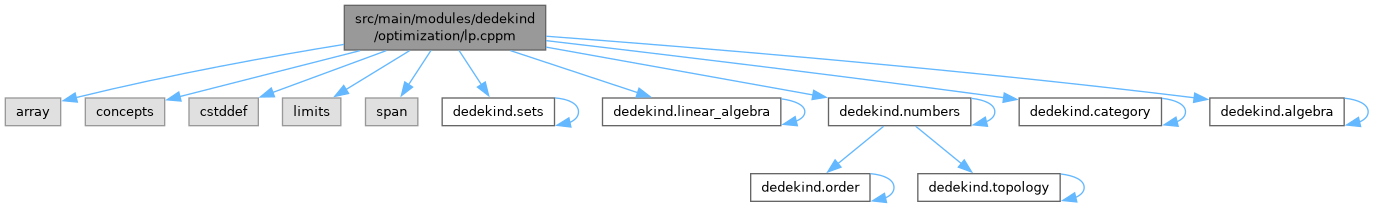
Classes | |
| struct | dedekind::optimization::Halfspace2D< T, a, b, c > |
| 2D halfspace a·x + b·y ≤ c, entries as NTTPs. More... | |
| struct | dedekind::optimization::HalfspaceTriple< T > |
Value-level halfspace carrier Halfspace2D<T, a, b, c> destructures into a HalfspaceTriple <T>{a, b, c} for the uniform value-vector the kernel consumes. The two structures share one role — the halfspace — split across the type/value boundary the bridge straddles. More... | |
| struct | dedekind::optimization::VertexCandidate< T > |
| Reduction output: optimum coordinates with a feasibility flag. More... | |
| struct | dedekind::optimization::LPSolutionPredicate< T > |
| |
| struct | dedekind::optimization::Singleton2DPredicate< T, x_val, y_val > |
| |
| struct | dedekind::optimization::Polytope2D< T, cx, cy, Hs > |
| Polytope context: the (cx, cy, Hs...) pack reified as a type. More... | |
| struct | dedekind::optimization::Halfspace2DPredicate< T, a, b, c > |
| |
| struct | dedekind::optimization::Polytope2DPredicate< T, Hs > |
| |
| struct | dedekind::optimization::LinearFunctional< T, cx_, cy_ > |
| Linear functional U : F → T with NTTP-typed coefficients. Carries the objective as type parameters so argmax can call the NTTP-driven implementation detail::maximize_set directly without smuggling the values through function parameters. More... | |
| struct | dedekind::optimization::Vec2< T, x, y > |
| Structural 2-tuple with coordinates at the type level. More... | |
Namespaces | |
| namespace | dedekind::optimization::detail |
Concepts | |
| concept | dedekind::optimization::SuitableForAxisAlignedFastPath |
| Carrier requirements for the bit-ops fast-path kernel. | |
| concept | dedekind::optimization::HasUnitRangeEntries |
| Pack-level concept: every halfspace has entries in {−1, 0, +1}. | |
| concept | dedekind::optimization::IsAxisAlignedPolytope |
| Pack-level concept: every halfspace is axis-aligned. | |
Typedefs | |
| template<typename T> | |
| using | dedekind::optimization::detail::LPSolutionSet |
| template<typename T> | |
| using | dedekind::optimization::detail::LPSolutionIdF |
Functions | |
| template<typename T> | |
| constexpr bool | dedekind::optimization::detail::is_singular (const T &det) |
| Carrier-aware singularity predicate on the Cramer determinant. | |
| template<typename T> | |
| constexpr VertexCandidate< T > | dedekind::optimization::detail::solve_active_set (const HalfspaceTriple< T > &h1, const HalfspaceTriple< T > &h2) |
| 2×2 active-set solve for the intersection of two halfspaces, treated as equalities: a1 x + b1 y = c1, a2 x + b2 y = c2. | |
| template<typename T> | |
| constexpr VertexCandidate< T > | dedekind::optimization::detail::maximize_impl (std::span< const HalfspaceTriple< T > > constraints, T cx, T cy) |
| Argmax over feasible vertex-candidates under the objective cx · x + cy · y. The co-Kleisli argmax on the candidate path; returns {x*, y*, true} on success, {0, 0, false} on an empty feasible set. | |
| template<typename T> | |
| constexpr VertexCandidate< T > | dedekind::optimization::detail::maximize_impl_axis_aligned (std::span< const HalfspaceTriple< T > > constraints, T cx, T cy) |
| Bit-ops fast-path kernel for axis-aligned signed-unimodular polytopes. Sibling of maximize_impl ; same return shape, same constexpr-callable / runtime-callable bridge property. | |
| template<typename T> | |
| constexpr auto | dedekind::optimization::lp_runtime_solution_set (dedekind::linear_algebra::Vec2V< T > point, bool feasible) |
Lift a runtime optimal locus into a {point} when feasible, empty when not, with the same Set type either way. | |
| template<typename T> requires dedekind::algebra::HasRingOperators<T> | |
| constexpr auto | dedekind::optimization::maximize_with_values (std::span< const HalfspaceTriple< T > > halfspaces, T cx, T cy) |
| template<typename T> requires SuitableForAxisAlignedFastPath<T> | |
| constexpr auto | dedekind::optimization::maximize_axis_aligned_with_values (std::span< const HalfspaceTriple< T > > halfspaces, T cx, T cy) |
Runtime entry for the bit-ops fast-path kernel. Same shape as maximize_with_values ; the NTTP entry maximize statically gates this path via HasUnitRangeEntries and IsAxisAlignedPolytope , but the runtime entry is also reachable directly, so the kernel defensively validates each halfspace and collapses the result to the empty Set (the output Set's LPSolutionPredicate carries feasible == false at the value level) on: | |
| template<typename T> requires dedekind::algebra::HasRingOperators<T> | |
| constexpr auto | dedekind::optimization::maximize_cramer_with_values (std::span< const HalfspaceTriple< T > > halfspaces, T cx, T cy) |
| Power-user runtime entry that forces the generic Cramer kernel and bypasses the mechanical dispatch in maximize_with_values . Same shape and requires as maximize_with_values ; sibling of maximize_axis_aligned_with_values on the Cramer side. | |
| template<typename T, T x_val, T y_val> | |
| constexpr auto | dedekind::optimization::lp_singleton_set () |
Lift an NTTP | |
| template<typename T> | |
| constexpr auto | dedekind::optimization::lp_empty_set () |
The empty optimum: Ø over Vec2V<T>, the output of argmax when the LP is infeasible — a value, not a compile event. | |
| template<typename T, T cx, T cy, typename... Hs> requires (sizeof...(Hs) >= 2) && dedekind::algebra::HasRingOperators<T> | |
| constexpr auto | dedekind::optimization::detail::maximize_set () |
NTTP packaging on top of maximize_with_values returning a | |
|
template<typename T, T cx, T cy, typename... Hs> requires (sizeof...(Hs) >= 2) && dedekind::algebra::HasRingOperators<T> | |
| constexpr auto | dedekind::optimization::lp_extract (Polytope2D< T, cx, cy, Hs... >) |
ε / extract for the LP comonadic context. Provided as a free function so callers can write lp_extract(polytope) at the call site. | |
| template<typename T, T a, T b, T c> | |
| constexpr auto | dedekind::optimization::halfspace_set (Halfspace2D< T, a, b, c >) |
| Lift a Halfspace2D NTTP value into a :expressions Set whose predicate carries the halfspace structurally. | |
| template<typename T, T a1, T b1, T c1, T a2, T b2, T c2> | |
| constexpr auto | dedekind::optimization::structured_and (Halfspace2DPredicate< T, a1, b1, c1 >, Halfspace2DPredicate< T, a2, b2, c2 >) |
| Halfspace + halfspace → polytope of two halfspaces. | |
| template<typename T, typename... Hs, T a, T b, T c> | |
| constexpr auto | dedekind::optimization::structured_and (Polytope2DPredicate< T, Hs... >, Halfspace2DPredicate< T, a, b, c >) |
| Polytope + halfspace → polytope with the halfspace appended. | |
| template<typename T, T a, T b, T c, typename... Hs> | |
| constexpr auto | dedekind::optimization::structured_and (Halfspace2DPredicate< T, a, b, c >, Polytope2DPredicate< T, Hs... >) |
| Halfspace + polytope → delegate to the canonical direction. | |
| template<typename T, typename... Hs1, typename... Hs2> | |
| constexpr auto | dedekind::optimization::structured_and (Polytope2DPredicate< T, Hs1... >, Polytope2DPredicate< T, Hs2... >) |
Polytope + polytope → concatenate the halfspace packs. Without this overload, a right-associative meet (H1 & H2) & (H3 & H4) would fall through to the lambda meet in structured_and is that the structural collapse must not depend on how the source bracketed the meet. | |
| template<typename T, typename L, typename... Hs, T cx, T cy> requires (sizeof...(Hs) >= 2) && dedekind::algebra::HasRingOperators<T> | |
| constexpr auto | dedekind::optimization::argmax (const dedekind::sets::Comprehension< dedekind::sets::𝔸< dedekind::linear_algebra::Vec2V< T >, L >, Polytope2DPredicate< T, Hs... > > &, LinearFunctional< T, cx, cy >) |
argmax(G, U) on a polytope-Set and a linear functional. | |
Variables | |
| template<typename H> | |
| constexpr bool | dedekind::optimization::detail::entries_in_unit_range_v |
Per-halfspace check: | |
| template<typename H> | |
| constexpr bool | dedekind::optimization::detail::axis_aligned_v |
Per-halfspace check: at least one of | |
| template<typename T> | |
| constexpr auto | dedekind::optimization::detail::lp_step_arrow |
Shape-level F-algebra structure map on the output Set: an endomap representing the "active-set step" at the type level. Concrete LP folds close over halfspaces internally; the shape-level witness here is halfspace-agnostic, which is what F-algebra structure abstracts. | |
Detailed Description
Linear programming with the optimum as a typed constant.
@partition :lp
- Copyright
- 2026 The Dedekind Authors Licensed under the Apache License, Version 2.0.
lp__Overview
Compile-time 2D LP over a structural ring-like scalar (paper-facing carrier: Rational<long>). A problem instance is named at the type level — objective as two NTTPs, constraints as a pack of Halfspace2D<T, a, b, c> carriers. The reduction argmax(G, U) over a polytope-Set G and a LinearFunctional U returns the optimum as a Set whose predicate type carries (x*, y*) at the type level — "the optimum IS a type", literally, via the Set DSL.
lp__Comonadic_Framing
The reduction is structurally a co-Kleisli arrow. Conceptually:
Path<Vec2<T, x, y>> → Vec2<T, x*, y*>
i.e. a path of vertex-candidates (one per pair of binding constraints) with an objective-directed argmax extractor. This mirrors the Path co-Kleisli machinery in dedekind.sequences:path exactly in shape; the implementation uses NTTP parameter packs rather than a runtime Path<T> because the paper-facing claim requires the output at the type level, not as a constexpr value.
FIXME: unify with dedekind.sequences:path co-Kleisli arrows once an NTTP-friendly Path carrier lands (tracked informally; the conceptual pattern matches exactly).
lp__Paper_Facing_Showcase
maximize 3x + 2y subject to x + y ≤ 4 (H1) 2x + y ≤ 6 (H2) -x ≤ 0 (H3: x ≥ 0) -y ≤ 0 (H4: y ≥ 0)
→ optimum = Vec2<Rat, 2, 2>, objective value = 10.
Active set at the optimum: {H1, H2} — both non-axis-aligned. The 2×2 solve uses Invertible2x2<Rat, 1, 1, 2, 1> (det = -1), giving the ℚ-exact intersection (2, 2) without rounding.
lp__Scope
- 2D polytopes only (rank-2 narrowing from #364).
- Feasible + bounded inputs only. An infeasible polytope (empty feasible region) surfaces as VertexCandidate::feasible == false on the returned candidate; callers inspect that flag on the result of maximize_with_values(). Unbounded polytopes are not detected by this reduction: enumeration returns the best vertex among the ${n \choose 2}$ active-set candidates, so an unbounded objective over an unbounded polytope will yield a finite vertex that is not the true supremum. The paper-facing showcases are bounded by construction; unbounded-LP detection is tracked as a follow-up.
- Carrier must (today) satisfy HasRingOperators<T> plus division and comparison, matching the actual Invertible2x2 Cramer solve below. The requires clauses are deliberately weaker than what the body needs — tightening to HasFieldOperators<T> plus an ordering requirement, or to a proper IsField<T, +, *> once the latter lands in dedekind.category:total, is tracked under epic #374 (algebraic concept vocabulary alignment). Paper-facing T = Rational<SignedExtensionalCardinal<>> covers all the real requirements; Dual<Rational<...>> layering works for parametric sensitivity analysis ([dual]-tagged test).
- Note
- "Modellbildung ist die halbe Miete." (Modelling is half the battle.) — Operations-research folk wisdom.
Function Documentation
◆ argmax()
requires (sizeof...(Hs) >= 2) && dedekind::algebra::HasRingOperators<T>
|
constexprexport |
argmax(G, U) on a polytope-Set and a linear functional.
G is a Set whose predicate is a Polytope2DPredicate carrying the halfspace pack; U is a LinearFunctional carrying the objective coefficients as NTTPs. Extracts both packs from the type level and dispatches to the kernel via detail::maximize_set , returning the optimal locus as a Set — singleton {(x*, y*)} when the LP has a unique optimum, empty when infeasible.
Set in, Set out: the textbook argmax : Set → Set shape, with both input and output carried by the project's set- comprehension DSL. The output Set's predicate type encodes the mathematical regime — caller pattern-matches on decltype(opt) if they want compile-time regime discrimination.
◆ maximize_axis_aligned_with_values()
requires SuitableForAxisAlignedFastPath<T>
|
constexprexport |
Runtime entry for the bit-ops fast-path kernel. Same shape as maximize_with_values ; the NTTP entry maximize statically gates this path via HasUnitRangeEntries and IsAxisAlignedPolytope , but the runtime entry is also reachable directly, so the kernel defensively validates each halfspace and collapses the result to the empty Set (the output Set's LPSolutionPredicate carries feasible == false at the value level) on:
- any coefficient outside {−1, 0, +1} (e.g.
h.a=2would otherwise read as+1·x); - a halfspace with both coefficients nonzero — diagonal, not axis-aligned (
x+y≤cwould otherwise read asx≤c); h.catstd::numeric_limits<T>::lowest()on carriers wherenumeric_limitsis specialised (signed integers):zero−h.cwould be undefined behaviour there.
Honest Rejection per the project's discipline. Constexpr-callable for compile-time evaluation; the runtime call site sees an IR without MUL or DIV on the carrier.
Carrier constraint SuitableForAxisAlignedFastPath names every operation the kernel uses ( T{} , T{1} , ring ops, ordering, signedness via (T{} − T{1}) < T{} ) so unsupported carriers fail at the API boundary rather than inside the function body.
◆ maximize_cramer_with_values()
requires dedekind::algebra::HasRingOperators<T>
|
constexprexport |
Power-user runtime entry that forces the generic Cramer kernel and bypasses the mechanical dispatch in maximize_with_values . Same shape and requires as maximize_with_values ; sibling of maximize_axis_aligned_with_values on the Cramer side.
Intended for callers who already know they want Cramer (e.g. IR fixtures isolating the kernel's residual fdiv + fmuladd signature, or microbenchmarks). Library default users should call maximize_with_values and let the type system pick the kernel from the input's structure.
◆ maximize_with_values()
requires dedekind::algebra::HasRingOperators<T>
|
constexprexport |
lp__The_Bridge
maximize_with_values is the single user-facing entry point for the 2D LP reduction. It is constexpr, takes a std::span<const HalfspaceTriple<T>> and a (cx, cy) objective, and delegates to the constexpr kernel detail::maximize_impl. Selection between evaluation modes is a property of the call site:
- Called with a span over a
constexprstd::array(e.g. from maximize, which materialises the NTTP pack), every argument is a constant expression and the call folds at translation time. - Called with a span over runtime data (e.g. a
std::vectorpopulated from a Python list of triples through the nanobind facade), the arguments are not constant expressions and the call runs at runtime.
One function, two modes — the paper's two-way bridge between value and type-level evaluation literally collapsed onto one definition. The compile-time packaging surface maximize sits on top of this entry to lift the result back into an NTTP Vec2<T, x*, y*>; it is the only thing in this file that performs the type-level lift.
◆ structured_and()
|
constexprexport |
Halfspace + halfspace → polytope of two halfspaces.
lp__structured_and_overloads
Customization point: when :expressions::operator& meets two predicates, it tries structured_and(p1, p2) via ADL before falling back to a lambda meet. Our overloads here let the DSL recognise halfspace + halfspace, polytope + halfspace, and halfspace
- polytope meets as structural reductions producing a Polytope2DPredicate that carries the union of the two halfspace packs.
Parallels :order:halfspace::structured_and on 1D halfspaces; the difference is that 1D meets land in Singleton / Interval / empty (the lattice for 1D), whereas 2D halfspace meets land in Polytope2DPredicate (no cardinality-1 short circuit at this layer — the optimum-as-typed-constant collapse happens further down in argmax via maximize ).